In June 2026, I wrote a page in my journal that eventually became a song.
By the time I released I Knew This Time Would Come, that page had become 58 rounds of generation in Suno, a working title (Blanket in the Field), several rounds of lyric changes, and a final pass by a human sound engineer.
The cover had its own history. It started with a photograph of me, went through an image generator, and was refined with my creative director until the figures looked like me again.
If someone asked me ten years from now where the song came from, I could point them to a Google Drive folder and my own account of what happened.
But the files themselves would tell a very different story.
That was the starting point for Intent Origin.
Listen to the finished song
I Knew This Time Would Come
0:00 / 0:00
The question wasn't entirely mine
Once I started looking into it, I found that other people were already trying to solve parts of the problem I had stumbled into.
C2PA's Content Credentials was being developed as an open technical standard for recording where a piece of digital media came from and what happened to it along the way. Google was adding provenance information to images generated with Gemini, while music platforms such as Deezer and Spotify were beginning to make AI involvement in music more visible.
Regulation was moving in a similar direction. The EU AI Act's transparency requirements were scheduled to take effect in August 2026, requiring certain AI-generated or manipulated content to be identifiable, while California's AI Transparency Act was set to take effect at the same time. The U.S. Copyright Office was also asking applicants to disclose AI-generated material and describe the human contribution to a work.
What my files showed me
So I went back to the files I already had and looked at what they could tell me about the history of the release.
The first cover concept had quite a lot to say. It carried a chain of 17 signed Content Credentials from Google, recording that the image had been created with generative AI, watermarked, converted, and resized.
What it couldn't tell me was where the image had really begun. It didn't know that the starting point was a photograph of me, taken a year earlier, or that the idea was to show two versions of me: one sitting still on a bench, the other walking past. It couldn't tell me about the conversations with my creative director, or the repeated attempts to get the faces to look like us rather than like generic generated people.
None of that record reached the cover I released. After my creative director refined the likeness and added the title, the final file carried no credentials at all. The history the machine had kept stayed behind on an intermediate file that no one outside my Drive would ever see.
The audio file had no provenance from the start. It didn't know about the journal page that started the song, the working title Blanket in the Field, the 58 rounds of generation in Suno, the lyric revisions, or the final work by the sound engineer. (Suno now attaches Content Credentials to songs on download; my file predates that change, so the difference between a documented work and an undocumented one came down to timing.)
Neither of the files I released remembered how it came to be. What history existed was spread across my Drive, one intermediate image, and my own memory.
What happens when everything has a history?
Imagine that by 2036, provenance records have become a normal part of publishing creative work. The systems we are beginning to see today have become more capable and more widely adopted, so that an image, a recording, a video, or a campaign asset can arrive with a history attached to it: where it started, which tools were used, what was changed, and which parts were generated by a machine.
That would solve one problem, but it might create another. If every piece of creative work comes with a provenance record, the existence of a record stops telling us very much. Provenance becomes less like a distinguishing feature and more like file metadata: useful, expected, and easy to overlook.
The more interesting question might then be what kind of history the record contains.
A record could tell us that an image was generated with a particular model, edited in another application, and exported on a particular date. It could tell us that an AI system generated the vocals on a song, or that a human edited the final mix. But none of that necessarily tells us what the person making the work was trying to do, what they rejected along the way, which source gave them the idea, or why one version survived when the other 57 did not.
My journal was already making that question uncomfortable. The page that started the song was part of the history, but it was also part of my private life, and I had no intention of publishing the whole thing simply because it happened to be the source of a finished work.
So the question became less about whether a creative work should have a provenance record, and more about what we would choose to put into one.
So I built a prototype
I wanted to see what a record like this might look like, so I built Intent Origin, a working prototype for documenting how a piece of creative work came to be.
The idea is fairly simple. You name the finished work, add the sources it began with, and build a timeline of what happened in between: a generative tool, a human collaborator, something you changed yourself, different versions of the work, and eventually the outputs that made it into the world.
What mattered more to me than the interface was making a distinction between different sources of knowledge. Some things can be established by the system itself, such as a file's size, creation date, or fingerprint. Some information comes from a tool, such as the Content Credentials attached to a generated image. And some notes can only come from the person making the work: when an idea began, what they were trying to do, who contributed, or why they chose one version over another.
Intent Origin keeps those categories separate rather than presenting them all as equally certain. Each piece of information is identified as system-observed, tool-declared, or creator-declared, and the record ends by stating what it cannot establish.
I also wanted to see what happened when the record was applied to something real, rather than invented as an abstract example. So I ran my own release through it.
What happened when I used it on my own work
I ran the release through Intent Origin to see whether the record I had imagined could actually reconstruct the history I already knew.
The first problem appeared before I had even reached the song. I added the journal page that had started the whole thing, and the file told me that it had been created 87 days after the date I had written on the page. That was because I had photographed the page later, when I began documenting the project. The software could establish when the photograph was taken, but it couldn't establish when I had actually written the page. For that, it had only my word.
That seemed like a small distinction, but it was exactly the kind of distinction I wanted the prototype to expose. The record could preserve my account of what happened without turning my account into a fact.
The song exposed the opposite problem. I knew that Suno had generated the vocals, arrangement, instrumentation, and melody across 58 rounds, but the finished audio file contained none of that history. It didn't know about the working title Blanket in the Field, the lyric revisions, or the final pass by a human sound engineer. The only trace in Intent Origin was the account I entered myself. The system could record my statement about what happened, but it had no independent way to verify it.
Then the prototype started finding problems in its own assumptions. In testing, it accepted a version dated months before its supposed source, allowed a contribution whose result file was identical to the finished output, and issued a record without commenting on the contradictions. I didn't want those cases to be silently "fixed" by the system, because some apparent contradictions might be legitimate. Instead, I added review notes to flag them without blocking the record.
I also found that even when provenance exists, reading it isn't necessarily straightforward. When I examined the credentials on the cover more closely, the first view showed only some of the recorded actions and didn't surface all of the information I knew was there. The record existed, but understanding it required looking past the first layer.
That, I realized, was part of the point. A useful provenance record might not be one that tells us everything. It might be one that makes clear what we know, what someone is telling us, and what remains unknown.
Which leaves me with two questions I don't think the prototype can answer: how much of a creative history should be independently verifiable, and how much should simply be preserved as someone's account of what happened? And who gets to decide what belongs in that history in the first place?
The full record
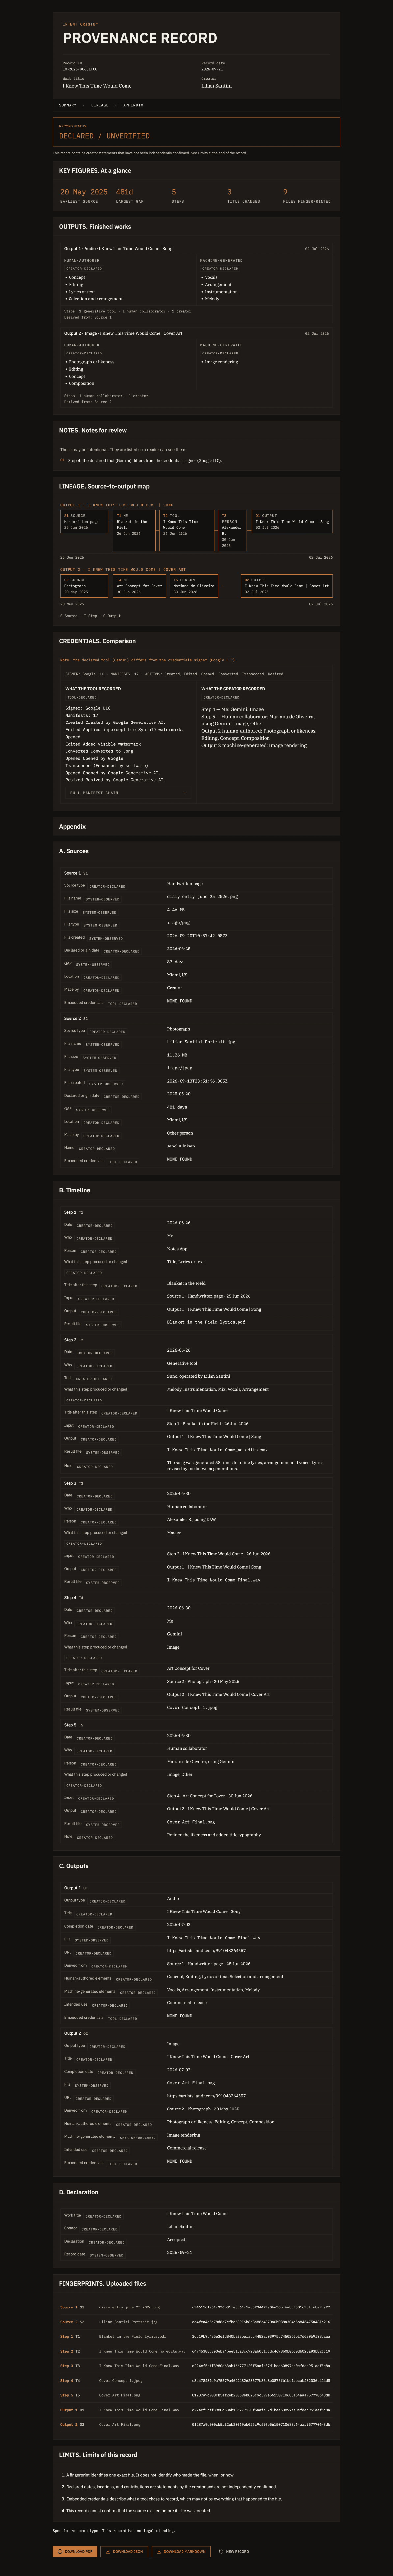
The complete record issued for this release. Scroll inside the box to read it.
View the full recordFor creative and brand teams
For creative teams, a provenance record could eventually become useful for reasons that have little to do with proving whether AI was involved. It could preserve the history of an important asset as it moves between people, tools, agencies, and platforms, particularly when the people who made the original decisions are no longer in the room.
It might mean knowing where an image actually began, what a generative system was given, which contributions survived into the final work, and who made the decisions along the way. It raises practical questions that teams will have to answer for themselves: what is worth preserving, who maintains the record, and what happens to that history when a project changes hands?
If provenance becomes commonplace, the more interesting record may not be the one that proves AI was disclosed. It may be the one that helps someone understand how this particular work came to be.
That's still an open question. I built Intent Origin to explore it, not to decide what every creative team should preserve.
Signals to watch
I don't know which version of this future will emerge, but there are a few developments I would keep watching.
Whether AI disclosure expands into contribution disclosure.
Music platforms are already moving beyond a simple AI/not-AI distinction, but it remains to be seen whether standards will begin recording more of the human roles and decisions involved in making a piece of work.
Whether provenance follows the work across formats and platforms.
A record is only useful if it survives the places where creative work actually travels. Screenshots, exports, edits, transcoding, and movement between tools can all create gaps in the history.
Whether provenance becomes standard in audio as well as visual media.
Images already have relatively mature provenance infrastructure, while music raises different technical and practical questions about how a history of generation, editing, performance, and contribution might travel with a recording.
Whether institutions begin asking for process, not just disclosure.
Copyright offices, platforms, clients, and other gatekeepers may eventually care not only about whether AI was used, but about what a human actually contributed to the finished work. If that happens, the distinction between a machine-generated disclosure and a record of creative decisions becomes more consequential.
For now, I'm less interested in predicting which of these happens than in watching what changes. Each one would tell us something about what kinds of creative history become worth preserving.
Project information
- Project:
- Intent Origin
- Type:
- Speculative prototype
- Built with:
- Lovable
- Context:
- IFTF Futures Thinking specialization
- Link:
- intentorigin.com
How this was made
This project grew out of the Futures Thinking specialization from the Institute for the Future on Coursera, particularly its approaches to scanning signals, exploring alternative futures, and building artifacts from the future.
I built the Intent Origin prototype in Lovable and used AI assistants throughout the process to research signals, pressure-test the ideas, and help structure both the prototype and this case study. The questions, framework, test case, and conclusions are my own.
The prototype is intentionally unfinished in one important sense: it doesn't claim to solve provenance. It is an artifact for exploring what a richer record of creative work might look like, what it could tell us, and what it would still leave out.